

Before 2023, “Large Language Model” was a term reserved for research papers and niche machine learning circles. Then, ChatGPT happened. Almost overnight, LLMs transitioned from academic curiosities to a household name. While most people didn’t know what the “GPT” stood for, the shift was seismic: LLMs stopped being “AI experiments” and started becoming infrastructure.
In 2026, AI tools are no longer the exclusive playground of data scientists. They are the engines driving product roadmaps, GTM strategies, and operational workflows. For builders, PMs, and leaders, understanding how these models learn is no longer “extra credit”, it is essential context. Understanding the training pipeline removes the “black box” thinking, giving you the intuition to know why a model might hallucinate, where it can be pushed, and when a specific tradeoff is necessary.
Before we dive into the weeds, let’s look at the “Big Picture.”
The End-to-End LLM Pipeline
This diagram represents the mental scaffolding for the entire process. Every detail we discuss later maps back to one of these three distinct phases:
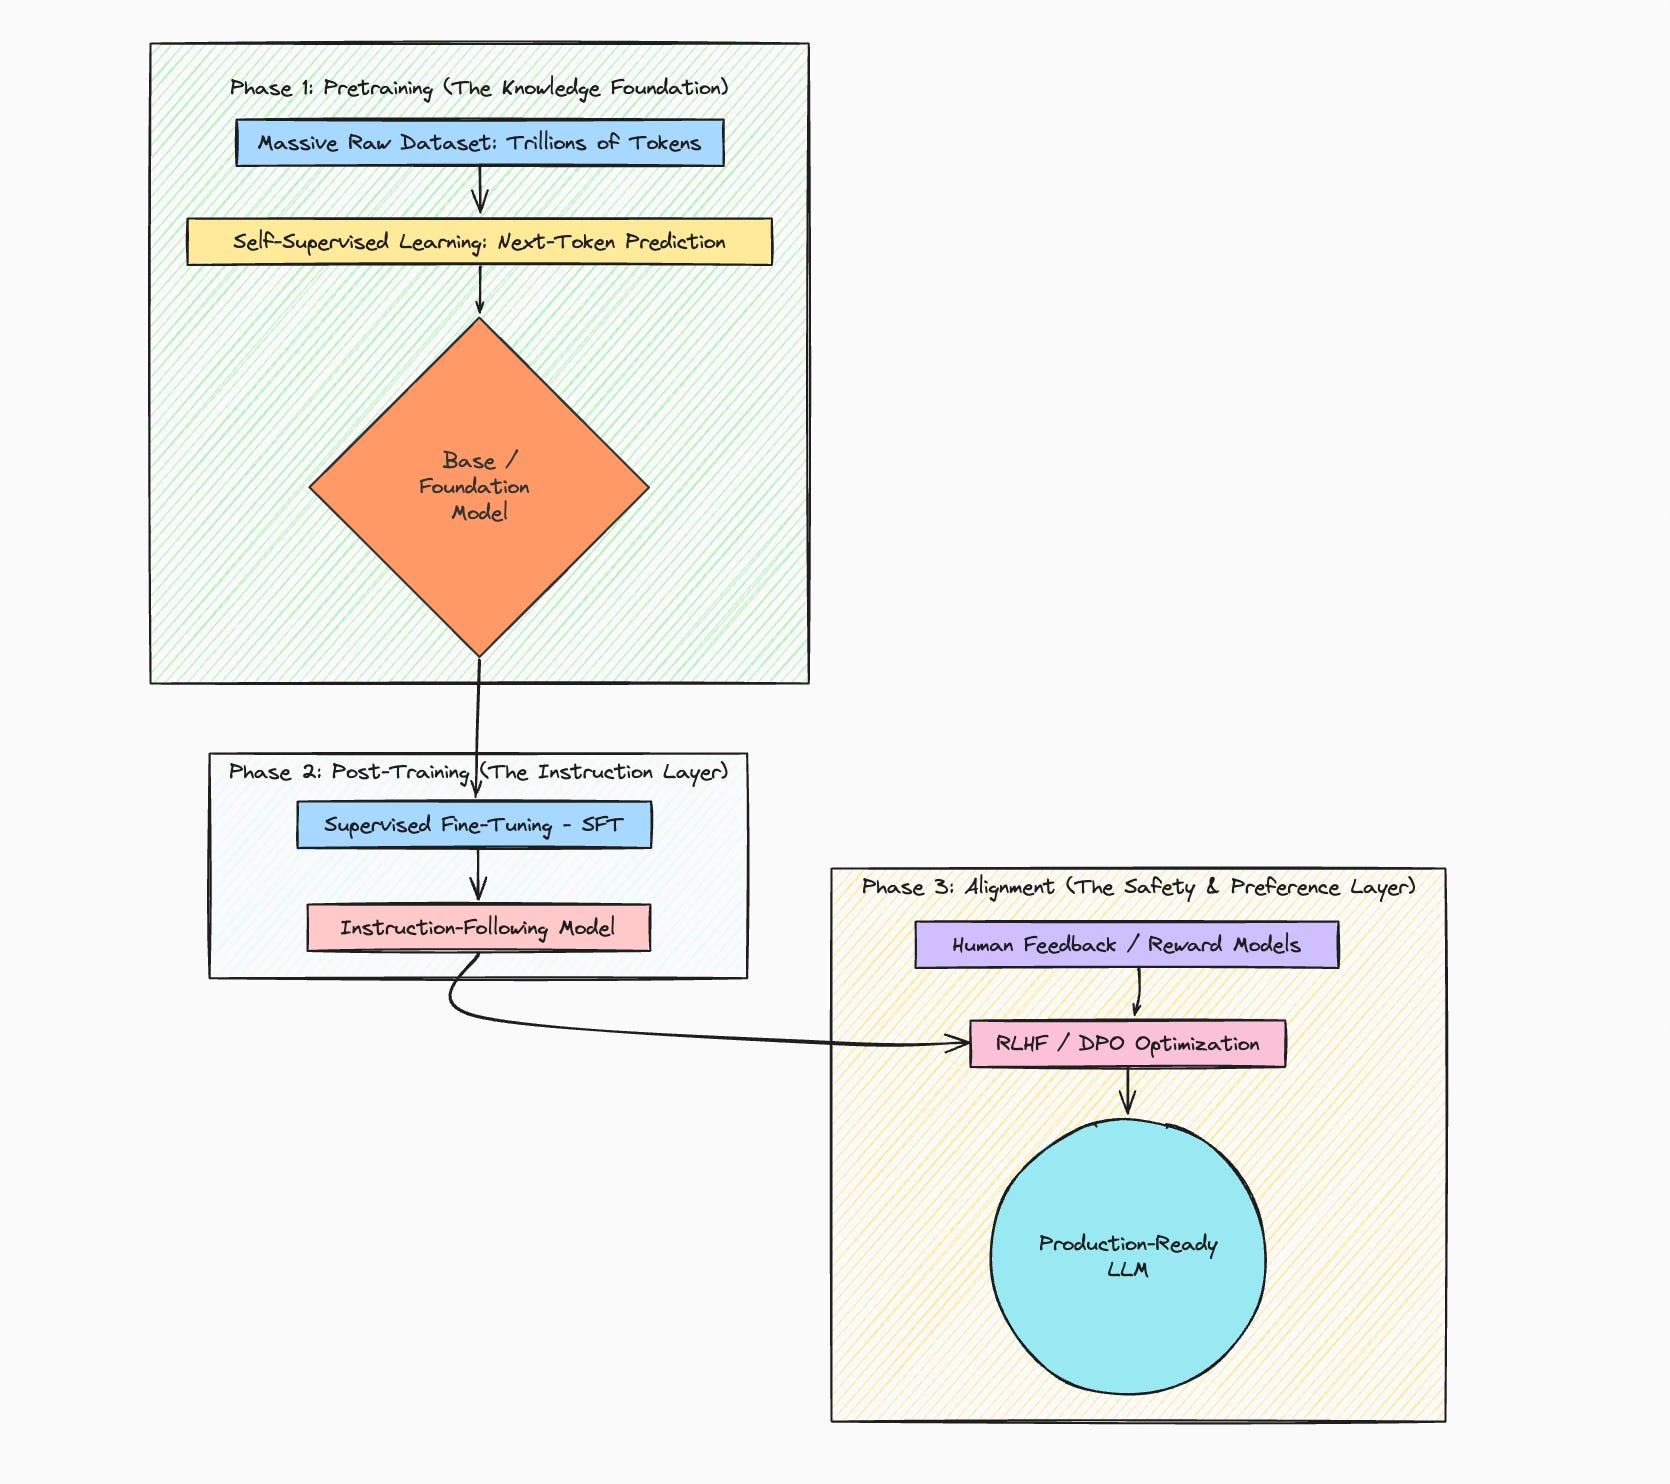
Phase 1: Pre-Training
Imagine trying to understand the entirety of human civilization by reading every book, article, and chat log ever written. That is pre-training. Even in 2026, this remains the most computationally expensive and data-intensive phase.
What is it?
ELI5: Pre-training is the “grammar school” phase. The model learns the structure of language, facts about the world, and basic reasoning patterns by playing a high-stakes game of “Guess the Next Word.”
Pre-training is where the model learns the statistical structure of language itself.
At this stage, the model is not being taught to be helpful, polite, safe, or aligned with human preferences. It is simply learning how tokens relate to one another across massive corpora of text. Given a sequence of tokens, it learns to predict the next token. That is it.
A good analogy is learning to read by consuming millions of books without ever being asked questions about them. You start recognizing grammar, syntax, facts, patterns, and long-range dependencies, but no one has yet told you how to answer a user, solve a task, or behave responsibly.
Pre-training produces a general-purpose language model. Everything else builds on top of this.
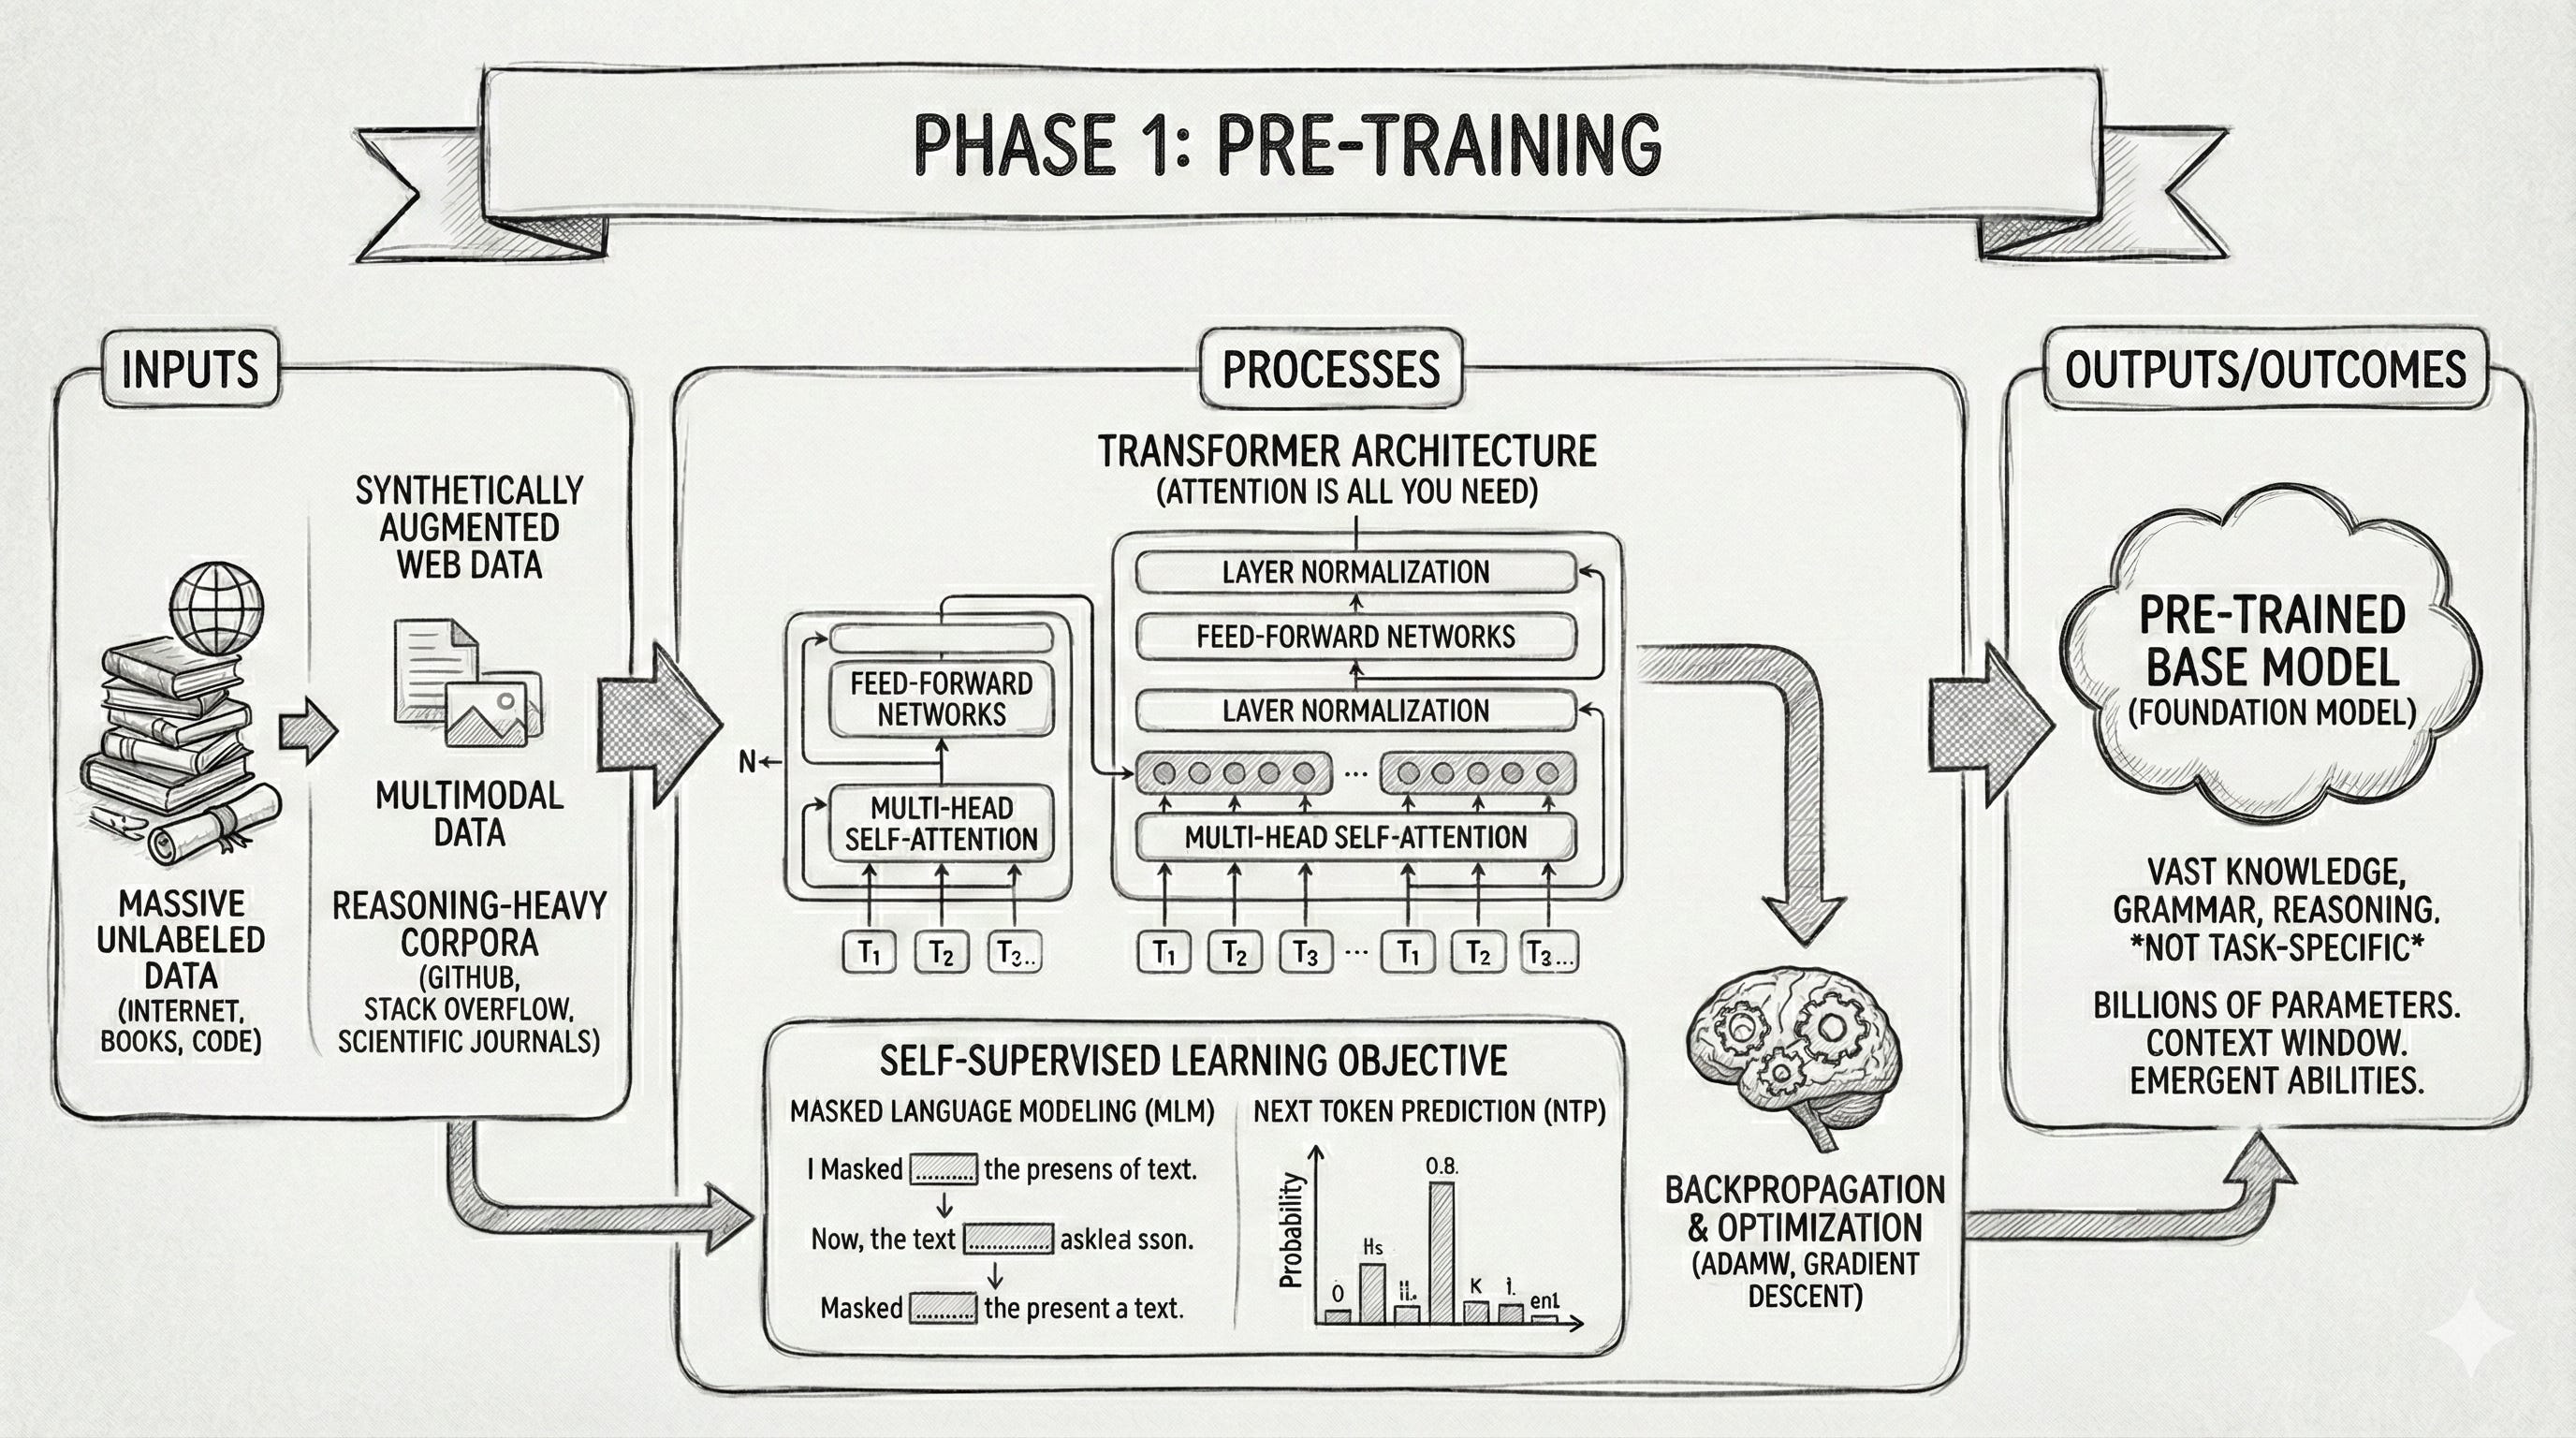
The Technical Data Stack
In 2026, we’ve moved past simple web-scraping. Pre-training datasets are now meticulously curated “Data Lakes” often exceeding 15–20 trillion tokens.
Synthetically Augmented Web Data: Cleaned versions of the open web where AI has been used to remove “junk” text.
Multimodal Integration: Modern pre-training often includes interleaved text and image tokens so the model “sees” the world while it “reads” about it.
Reasoning-Heavy Corpora: Massive dumps of GitHub repositories, Stack Overflow, and LaTeX-heavy scientific journals to bake in logical and mathematical reasoning.
This data is mostly unlabeled. There is no notion of “correct answers” or “preferred responses.” The supervision signal comes purely from next-token prediction.
On the infrastructure side, this phase relies heavily on:
Distributed training across thousands of GPUs or accelerators
High-throughput storage systems
Custom data pipelines for sharding, mixing, and curriculum scheduling
Fault-tolerant training frameworks
This is the most expensive phase of the entire lifecycle. Most organizations will only pre-train a foundation model once, then reuse it across many downstream applications.
The Process: The Objective Function
The core task is Next-Token Prediction. Given a sequence:
the model predicts ;
It minimizes the Cross-Entropy Loss:
Where theta represents the trillions of parameters being adjusted. By doing this billions of times, the model doesn’t just learn “words”; it learns the statistical probability that “The capital of France is...” will be followed by “Paris.”
During pre-training, the model:
Learns vocabulary and token representations
Builds internal representations of grammar and semantics
Encodes world knowledge implicitly through statistical correlations
Develops emergent capabilities as scale increases
What it does not learn is how to follow instructions, how to be truthful, or how to align with human values. A pre-trained model is powerful but raw. Think of it as an engine without a steering wheel.
Stage 2: Post-Training (Fine-Tuning)
If pre-training creates a “polymath who knows everything but can’t follow a simple direction,” post-training is the “professional certification” that teaches the model how to be useful. This is used to create specialization and refinement in the models.
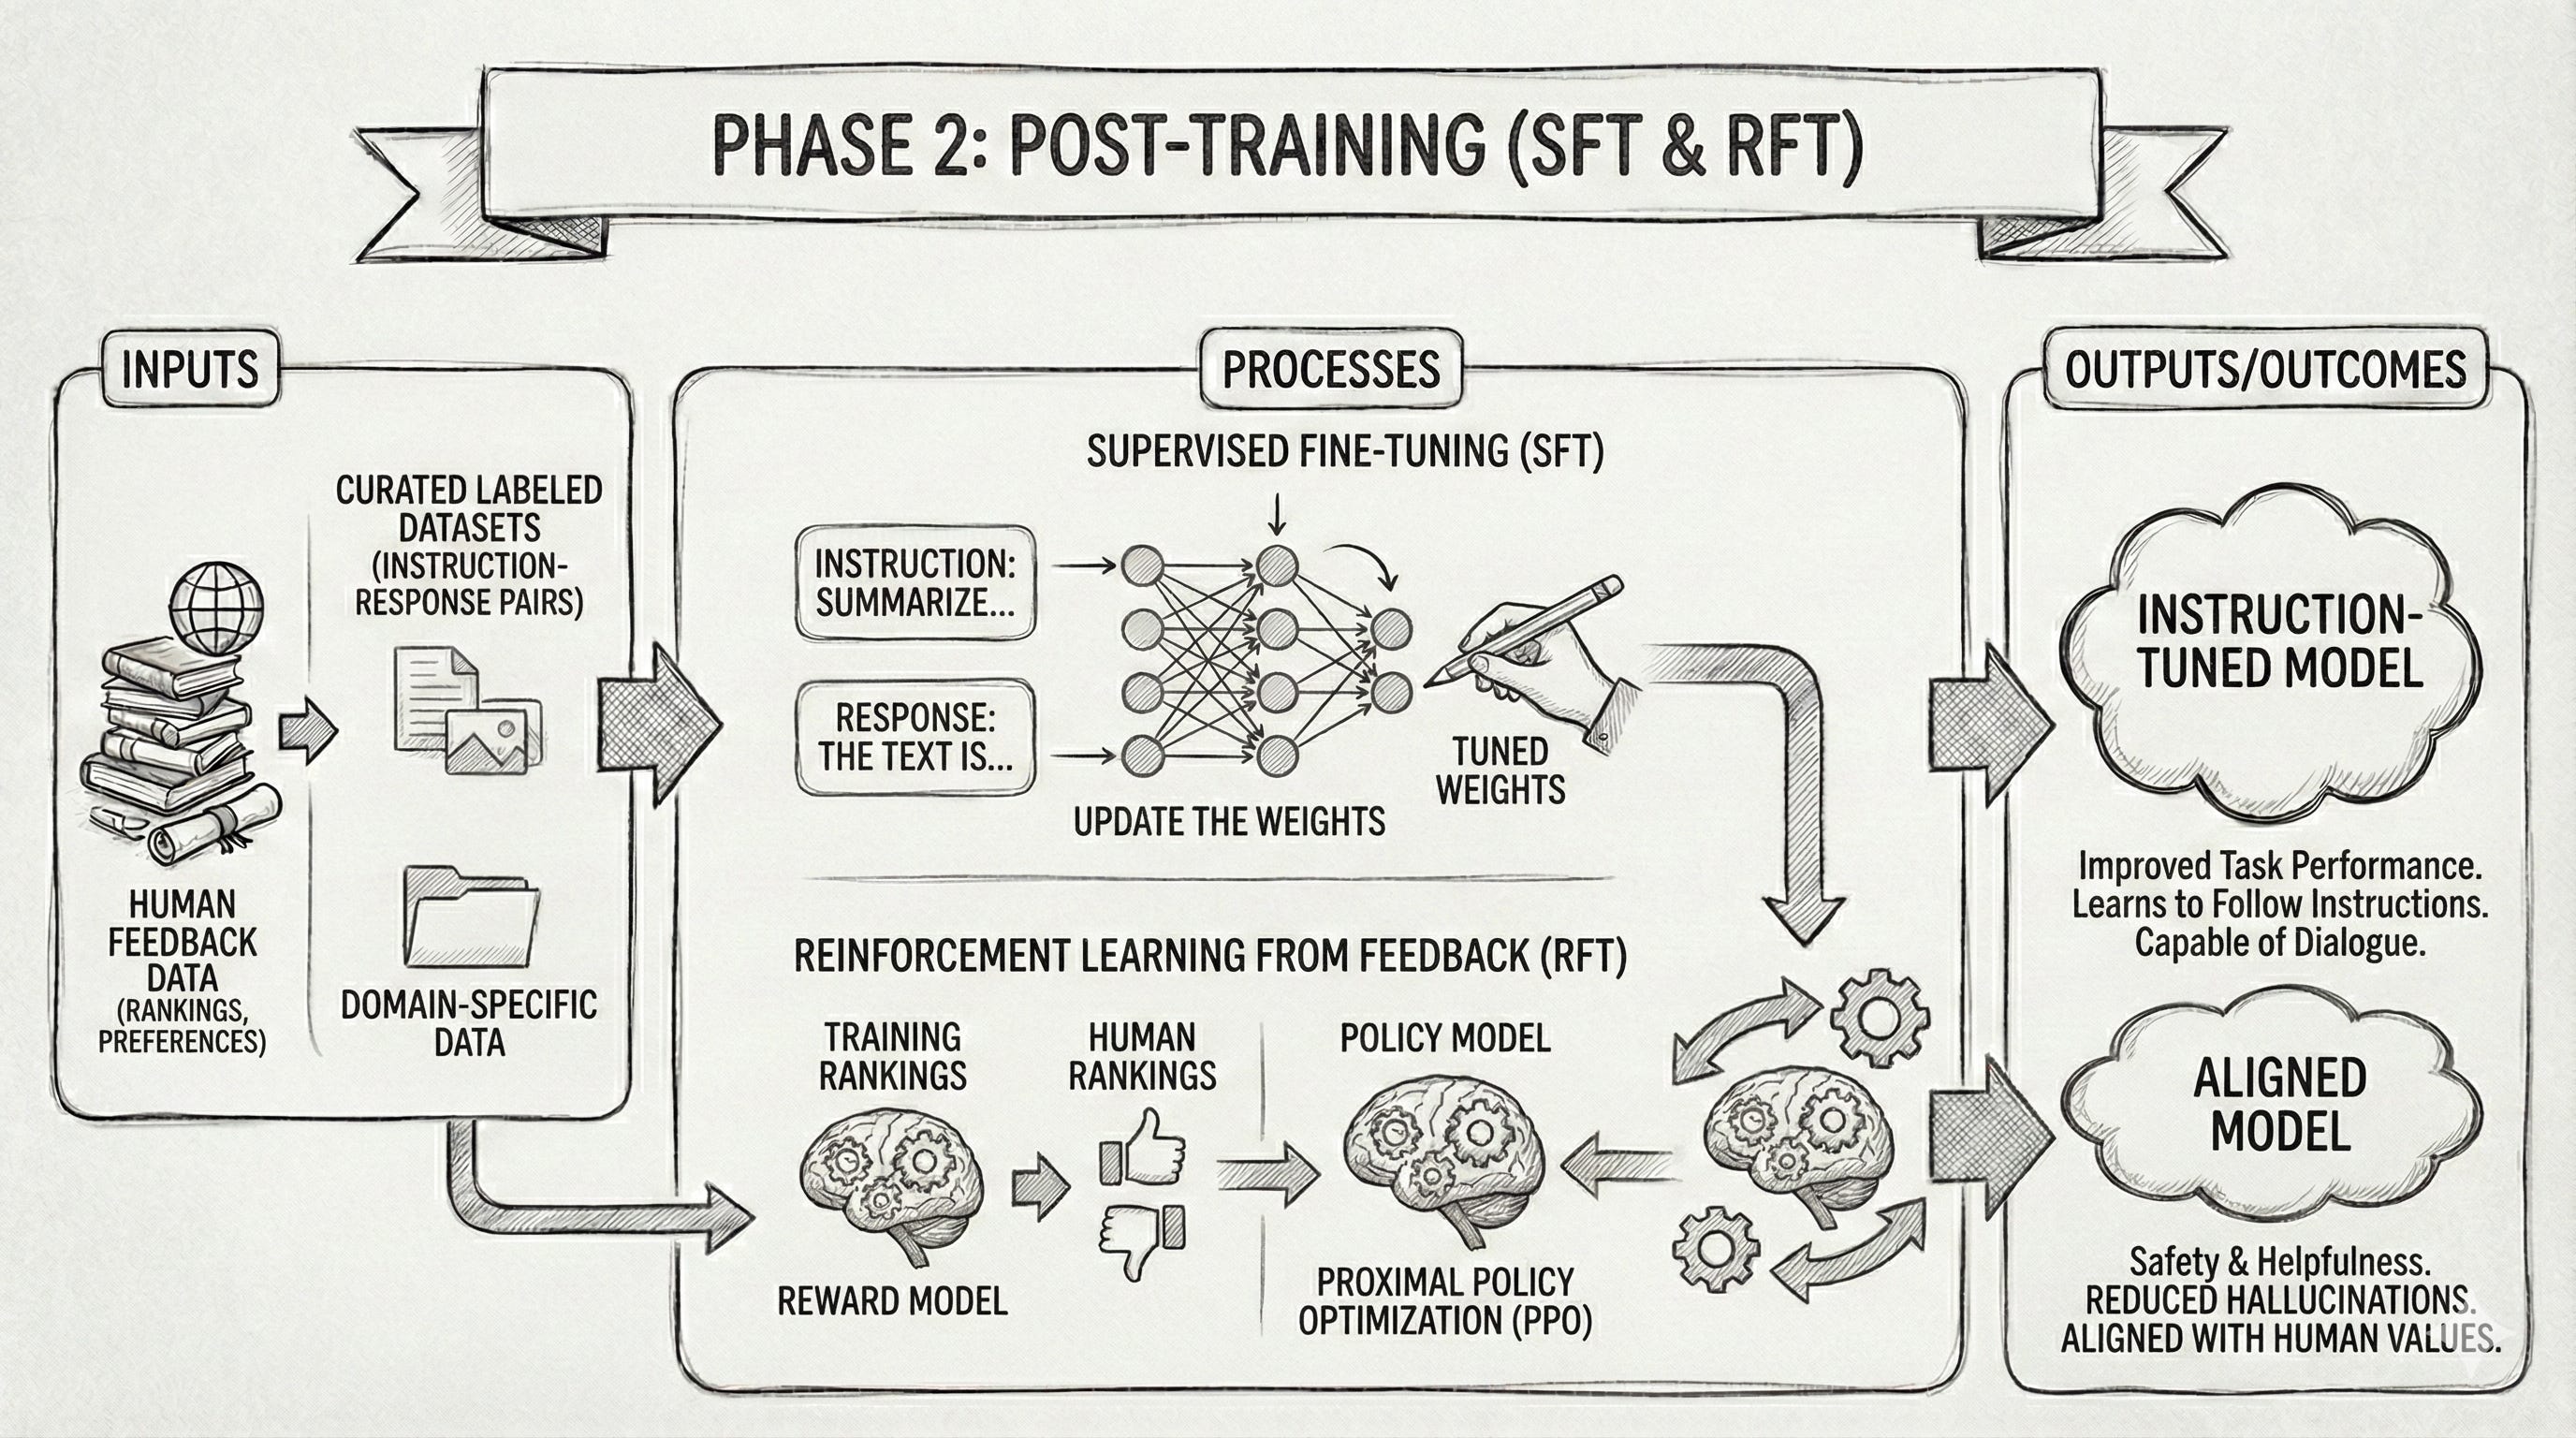
What is it?
Once you have a pre-trained model, the next question is simple: how do you make it useful? This is where post-training comes in.
ELI5: This stage, primarily Supervised Fine-Tuning (SFT) or Reinforcement Fine-Tuning (RFT), transitions the model from a passive document-completer to an active assistant. Instead of just “continuing” a sentence, it learns to “answer” a prompt.
Post-training adapts the general language model to specific tasks, domains, or behaviors. Instead of learning language from scratch, the model is now learning how to apply that knowledge.
Supervised fine-tuning (SFT)
Supervised fine-tuning is usually the first step in post-training.
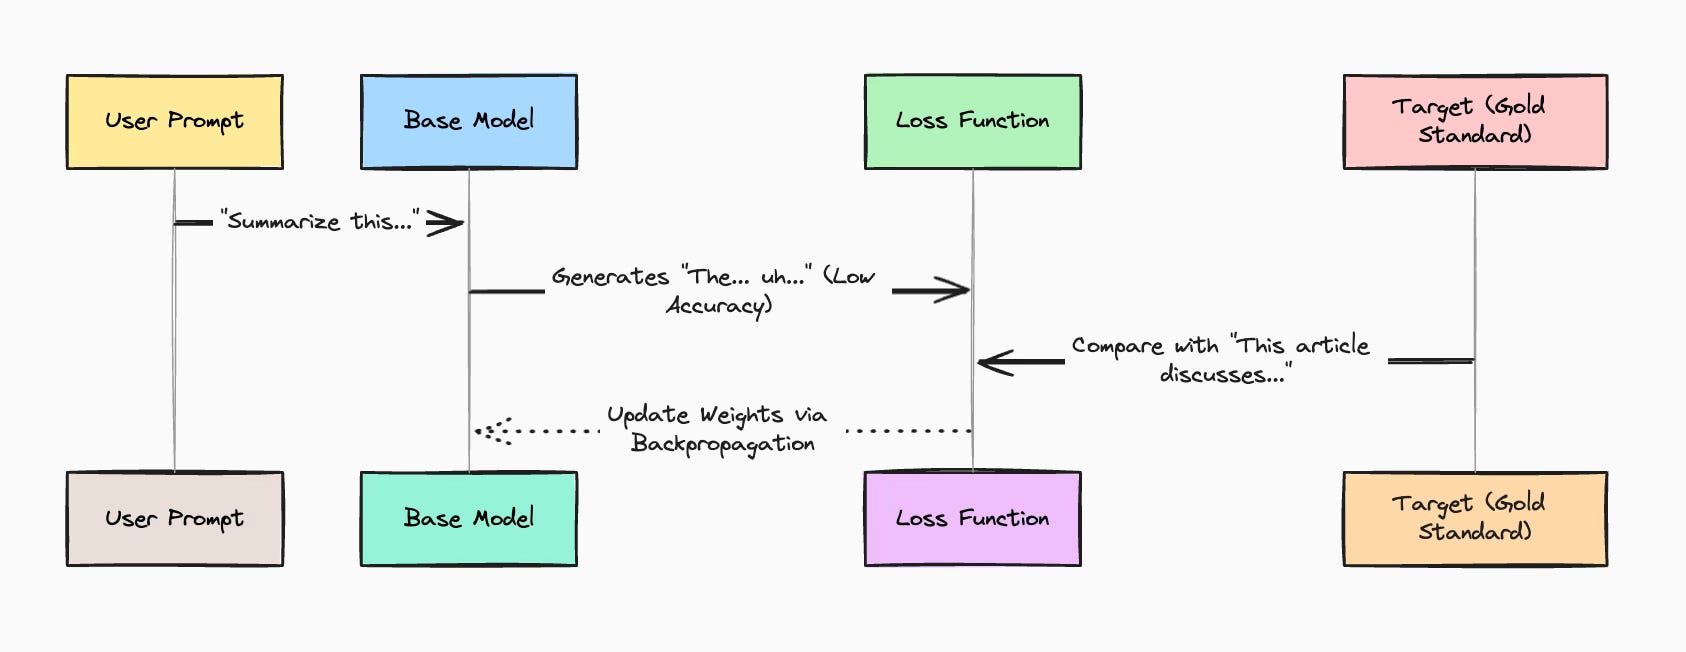
Here, the model is trained on curated input-output pairs. For example:
A question and a high-quality answer
An instruction and a desired response
A code prompt and a correct implementation
This phase teaches the model how to respond, not just how language flows.
SFT is especially useful when:
You want predictable behavior
You have high-quality labeled data
You are adapting a model to a specific domain like medical text, legal documents, or internal company knowledge
Unlike the trillions of tokens in pre-training, SFT uses high-quality, human-curated datasets (usually in the thousands or hundreds of thousands).
Prompt-Response Pairs: “Write a Python script to scrape a website” → [Correct Code].
Chain-of-Thought (CoT) Data: Training the model to “think step-by-step” by providing examples where the answer includes the intermediate reasoning.
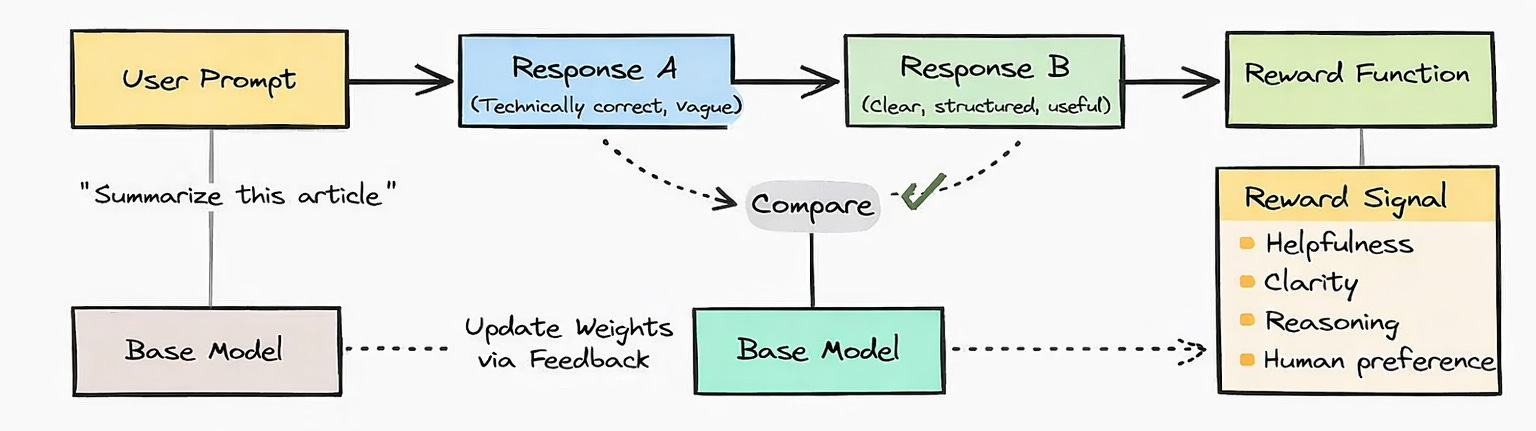
Reinforcement fine-tuning (RFT)
Supervised fine-tuning alone is often not enough, especially for open-ended tasks.
This is where reinforcement fine-tuning comes in.
Instead of training on fixed “correct” answers, the model generates outputs, receives feedback through a reward signal, and updates itself to maximize that reward.
Reinforcement fine-tuning is useful when:
There is no single correct answer
Quality is subjective or multi-dimensional
You care about reasoning, style, or long-term coherence
Examples include:
Improving reasoning depth
Optimizing for helpfulness or clarity
Training models to follow complex instructions
Unlike SFT, reinforcement fine-tuning does not rely on a single correct answer. Instead, it learns from comparisons between multiple model outputs.
The datasets are smaller than SFT, but the signal is richer.
The Result
The output is a model that understands the Instruction Format. It knows that when it sees “TL;DR,” it should provide a summary, not a list of unrelated acronyms.
